Recognizing a critical challenge in enterprise data architecture—separating data availability from data accessibility—HPE reached out directly to Loadbalancer.org to co-architect a unified solution. By combining the HPE Alletra Storage MP X10000 (HPE X10K) object storage platform with Loadbalancer.org's Global Server Load Balancing (GSLB) technology, this collaborative engineering addresses a crucial gap.
While HPE X10K ensures that object data is resilient, highly performant, and synchronized across clusters, a dedicated load balancer is needed to ensure that clients can actually reach the optimal storage node without hitting a bottleneck, experiencing high latency, or dropping connections during a site outage.
By combining the two technologies, and placing the fully qualified domain names (FQDN) of enterprise S3 buckets under the purview of Loadbalancer.org, storage traffic is no longer left to chance. Users can be intelligently steered to the optimal HPE X10K cluster site based on real-time health, proximity, and network performance—ensuring multi-site high availability that keeps pace with modern enterprise data demands.
What you'll learn:
- Overcome active-passive limitations: Discover how combining HPE Alletra Storage MP X10000 (X10K) with Loadbalancer.org Global Server Load Balancing (GSLB) replaces idle secondary sites with an active-active, high-availability architecture.
- Automate cluster scaling via CLI: Learn how to programmatically onboard and scale large HPE X10K node pools into GSLB configurations using automated
lbclibash scripts rather than manual UI updates. - Fix DNS delegation mismatches: Understand the DNS infrastructure requirement—delegating a dedicated storage subdomain zone—to ensure GSLB controllers properly return target node IPs instead of the load balancer's root IP.
- Optimize routing latency with EDNS0: Explore how enabling EDNS0 (DNS Client Subnet) passes original client subnet details through corporate DNS resolvers, enabling accurate topology- and proximity-based traffic steering.
- Deploy an HPE-validated blueprint: Review a proven, lab-tested integration architecture built for multi-site failover, asynchronous replication, and heavy S3 object storage workloads like multi-site Splunk.
The challenge: Separating data availability from data accessibility
Without Global Server Load Balancing (GSLB) in place, multi-site traffic distribution for object storage remains limited. Storage architects are often forced to rely on basic round-robin DNS or rigid active-passive deployment models. In an active-passive setup, one data center handles the primary storage workload while another sits idle as a hot standby, waiting for a catastrophic infrastructure or network outage to trigger a manual switchover.
HPE’s engineering team was acutely aware of these limitations and collaborated directly with Loadbalancer.org to leverage contextual routing—such as source IP awareness and network response measurements via the Client Subnet (EDNS0) extension—to guide storage traffic to the best possible landing site.
The primary objective: enable seamless, multi-site failover and asynchronous replication across HPE X10K nodes spanning multiple data centers.
The HPE-validated architecture
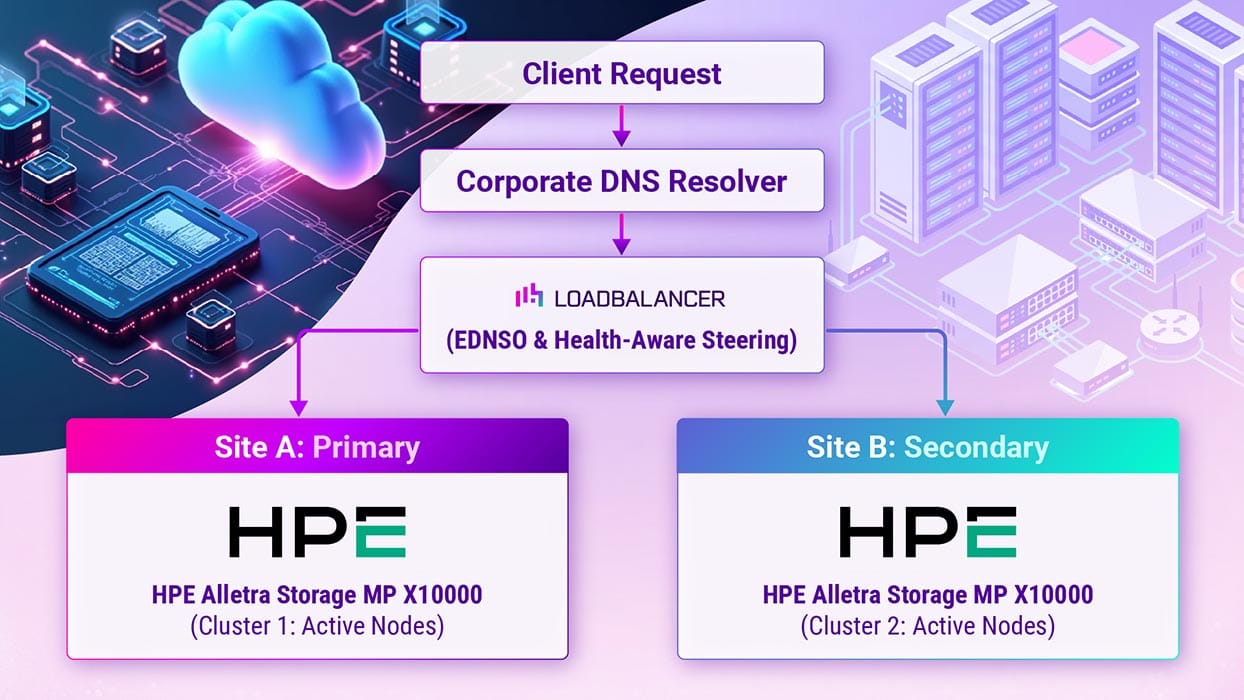
1. HPE Alletra Storage MP X10000 (HPE X10K)
The HPE X10K, engineered to handle massive, unstructured S3 object storage workloads with high resiliency. This is architecture built for exabyte scale, where keeping vast data buckets fast, perfectly synchronized, and constantly available across multiple geographical locations is paramount.
2. Loadbalancer.org GSLB
Loadbalancer.org’s smart Global Server Load Balancing (GSLB) uses real-time data and site-specific topology to intelligently route traffic, meaning it understands how your infrastructure is configured, as well as where your applications and users are located. This is critical for workflows that need unrestricted bandwidth, such as object storage and AI. The result is supercharged enterprise-applications with seamless multi-site failure if things go wrong.
The lab setup and validation environment
To demonstrate this capability, a joint team from Loadbalancer.org and HPE spun up a feasibility and integration validation environment.
The baseline setup for the lab environment was structured as follows:
- The use case: Multi-site Splunk
- The storage layer: HPE Alletra X10000 storage platform for S3, NFS and SMB.
- The GSLB infrastructure: Loadbalancer.org virtual appliances deployed as VMs within an enterprise ESX server environment.
- The topology: A multi-member GSLB topology focused heavily on verifying global steering, automated failover/failback, and granular DNS redirection.
Technical lessons and integration solved in the lab
During setup and validation, the joint team addressed key operational requirements for the multi-site HPE Alletra Storage MP X10000 and Loadbalancer.org Global Server Load Balancing integration, to ensure the solution scales smoothly in production enterprise environments:
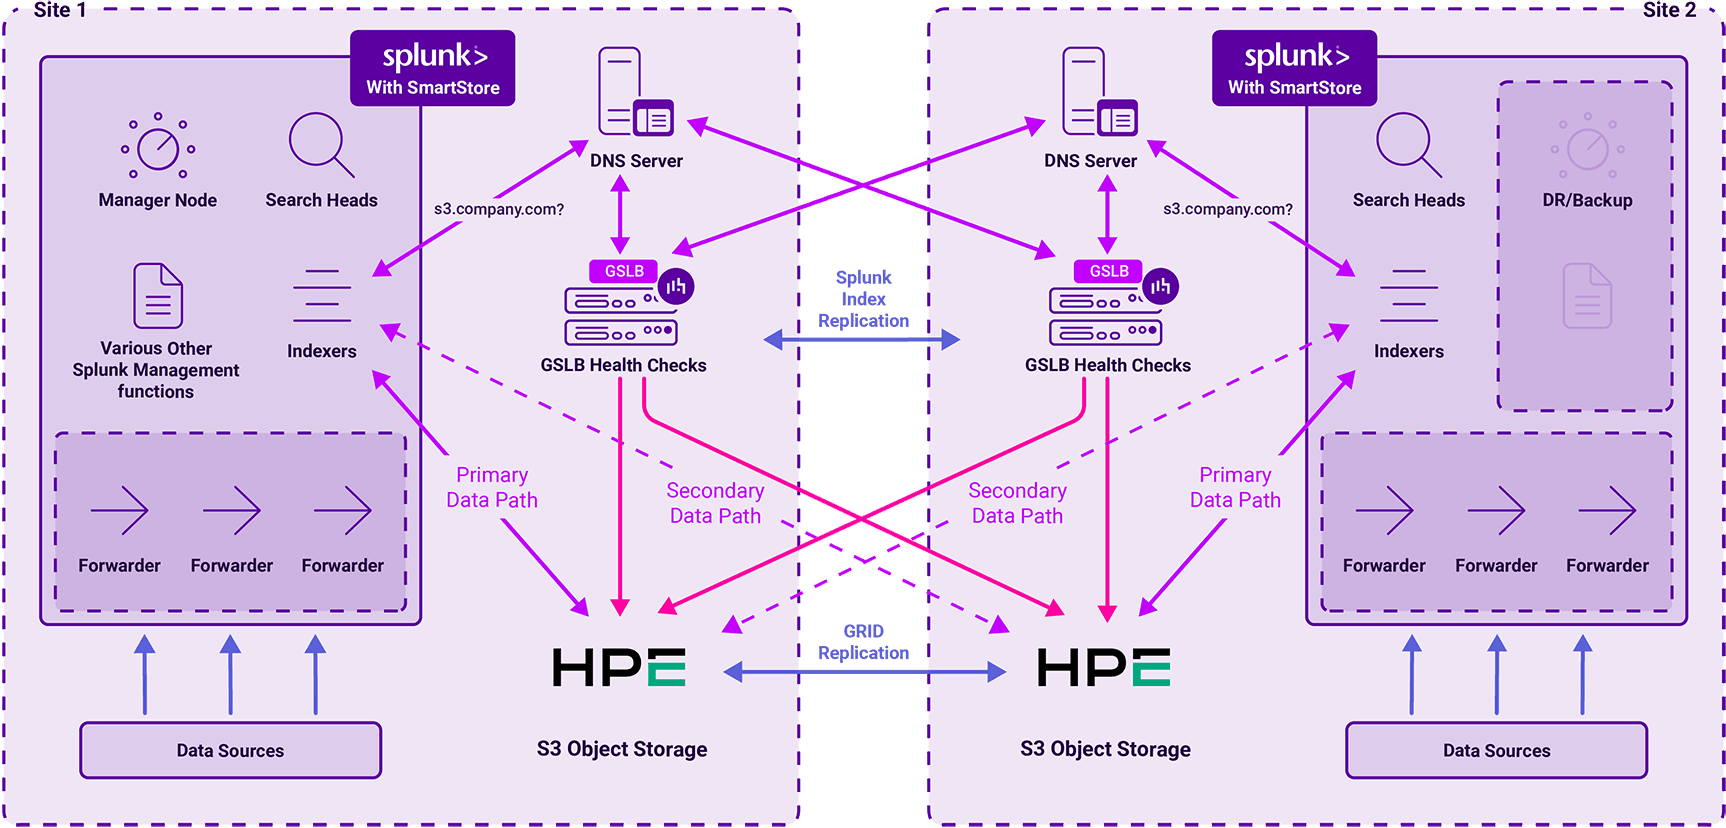
1. Programmatic scalability via CLI
During initial configuration, the HPE team sought programmatic guidance on mapping extensive node groups into the GSLB framework.
Rather than relying on repetitive Web-UI steps for bulk object storage cluster members, the team accomplished programmatic scale using the Loadbalancer.org Command Line Interface (lbcli). Administrators can automate the inclusion of large node pools with simple bash scripts:
# Example: Adding multiple HPE X10K cluster nodes to GSLB mapping via lbcli

lbcli add-gslb-globalname --name "HPE-X10K" --hostname "s3.hpe.com" --tll 0

lbcli add-gslb-pool --name "HPE-X10K" --add-globalname "HPE-X10K" --lb-method "twrr" --monitor http --monitor-use-ssl yes --monitor-url-path "/_healthcheck/"
node_ips=("192.168.10.11 192.168.10.12 192.168.10.13 192.168.10.14)

for i in ${!node_ips[@]); do
  lbcli add-gslb-member --name "srv${i}" --ip "${node_ips[$i]" --weight 10 --add-pool "HPE-X10K"
done
This scriptable approach ensures that as storage buckets or nodes dynamically scale out on the HPE X10K side, the delivery controllers adapt automatically.
2. Resolving subdomain delegation & FQDN alignment
During early DNS routing tests, an nslookup targeted at the storage endpoint returned the root IP address of the load balancer appliance itself rather than distributing the targeted IPs of individual GSLB cluster members.
The team identified the root cause as a corporate DNS delegation mismatch. In an active GSLB architecture, the main corporate DNS must formally delegate a dedicated storage subdomain to the load balancers, allowing them to act as the authoritative name servers for that specific zone.
The fix: The team configured a dedicated storage subdomain zone: gslb.ftc.storage.hpecorp.net. Once the FQDNs on the Loadbalancer.org appliances were updated to match this delegated zone, the system successfully intercepted S3 queries and served the backend IPs of the appropriate HPE X10K cluster nodes.
3. Latency optimization using EDNS0 Client Subnet
To refine client steering, the team verified the enablement of EDNS0 (Extension Mechanisms for DNS) within the upstream DNS servers.
When a client requests a storage endpoint through an upstream corporate DNS resolver, a load balancer typically sees only the IP address of the resolver—not the requesting client. With EDNS0 enabled, the resolver forwards the client's original subnet information. This allows Loadbalancer.org GSLB to make accurate topology routing decisions, sending data traffic directly to the nearest, lowest-latency HPE X10K node.
Architectural takeaways for storage leads and infrastructure teams
This validated blueprint gives enterprise teams a proven framework for multi-site high availability across file and object storage. By pairing HPE Alletra X10000’s built-in data resilience with Loadbalancer.org’s dynamic traffic management, architects can deploy without worrying about common integration or failover friction.
To get the most out of a multi-data-center deployment, keep these key operational practices in mind:
- Zone consistency matters: Ensure your internal DNS delegation zones and your ADC's FQDN settings are completely unified under the designated GSLB subdomain (e.g., gslb.yourstorage.domain.com).
- Leverage CLI for scalability: Avoid relying solely on UI operations when mapping large storage node pools. Utilizing automated lbcli scripting significantly accelerates data center expansion and reduces human error.
- Enable EDNS0 at the Edge: Without Client Subnet context, geographic and latency-based traffic steering reverts to guessing based on resolver locations. Enabling EDNS0 ensures traffic is routed based on the actual location of the storage consumer.
Conclusion: De-risk your HPE multi-site deployments
Designing multi-site high availability and asynchronous replication from scratch is complex. This joint validation demonstrates that HPE Alletra Storage MP X10000 and Loadbalancer.org GSLB work together seamlessly, providing a pre-tested, dependable blueprint for mission-critical enterprise object storage.
Audit your storage stack for performance bottlenecks.
Finally, a simple way to convert MaxMind GeoIP Database files to the legacy DAT format!
Related posts
Building resilient neocloud S3 storage architecture: The critical role of load balancing
Envoy proxy vs. purpose-built load balancing for object storage
How to load balance a MariaDB Galera Cluster for performance and HA using LVS & Ldirectord
How to use content-length headers to solve the 'small objects problem'
High zero-day in Citrix NetScaler ADC & Gateway: Patch CVE-2026-88779
Critical zero-day in F5 BIG-IP APM: Emergency CVE-2026-94127 hotfixes released
Critical zero-days in Citrix NetScaler ADC & Gateway: Patch CVE-2026-88771 and CVE-2026-88772 immediately
The ultimate VMware NSX alternative: Nutanix + Loadbalancer.org